October 16, 2026
Migrations turn code itself into state
Finding what you’re looking for
All answerable questions in life and in the universe can be restated as a search problem — in other words, all questions essentially boil down to figuring out how to find what you’re looking for. In software, the most generic (and most commonly used) answer to the question of finding what you’re looking for is a database. Databases help applications find the data they’re looking for in a reasonable amount of time (even when there is a lot of data) by letting engineers specify the shape of their data and the ways in which they will search for specific records. For example, phone books organize the data alphabetically by name. If you know someone’s name, you can quickly find their phone number. Being able to answer one question about the data does not mean you can easily answer other questions. For instance, you cannot (in any reasonable amount of time) find a name given a phone number.
SQL is a language that lets developers specify how their data should be organized and what kinds of records you can retrieve quickly. It’s used in pretty much everything that handles any non-trivial amount of data. And if you have ever used a computer in the last 30 years, it’s a certainty that part of your experience was powered by SQL. Unlike most computer languages that tell computers how to perform a task (step by step), SQL tells the computer what you want. It’s up to the database to decide how to fulfill the request. This quality of SQL makes using databases vastly easier than it otherwise would be and yet, building with SQL can be more challenging than writing other pieces of the app even in languages that require you to lay out step by step how something should happen.
Migrations: when the code is state
The problem is that software is always changing. There are bugs, new features, and new problems the code must solve over time. Ordinarily, this just means changing, adding, or deleting code. But changing how a database organizes its data requires “migrations” — a way of directing the database to its desired state given its current state. Because migrations are an inextricable part of life with SQL databases, (much of) SQL code is in practice run in the same order it’s written, which means that in order to understand what any single bit of SQL does, you have to understand every bit of SQL that was run previously… which means it gets harder and harder to write more code as the code base grows.
Consider the difference between these two programs controlling a robot:
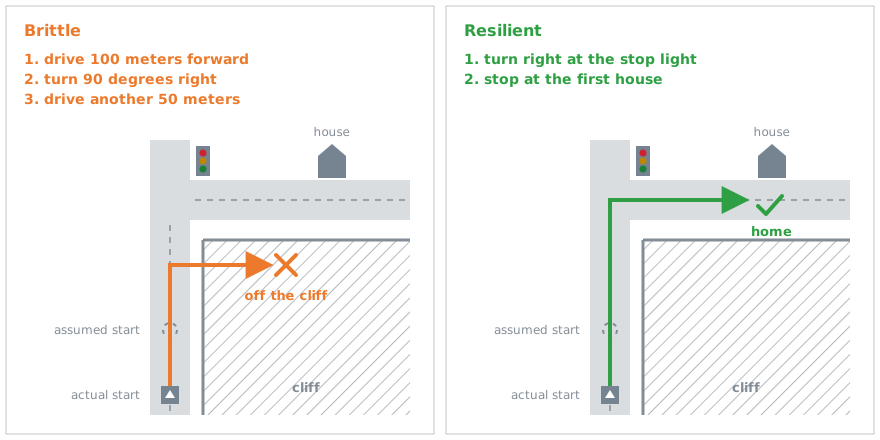
The brittle version is obviously longer (which generally means more complexity, which generally means more bugs) but the key issue is that like SQL in practice, each instruction requires you to understand all previous instructions to understand what the current instruction does. Consider the line turn 90 degrees right. Depending on where you are, turning 90 degrees either takes you through the stop light or it drives you off a cliff. The consequences of the command itself cannot be understood without understanding all prior commands and where they’ve landed you. The same is not true of turn right at the stop light. You can certainly turn at the wrong stop light if you run that command at an unexpected time, but you aren’t going to turn into a car, a house, a wall, or off a cliff, because you were not where you thought you were when the command was called. It’s much easier to reason about, build, and maintain.
This is why handling state is something most good engineers try to squeeze into the smallest volume of code possible. It’s why the entire family of functional languages exists. But with SQL, it’s not just that the code is handling state, it’s that the code itself is state. There’s a reasonable reason for this: the database, unless it’s empty, is state, so changes to how it works need to consider what’s in it.
This is so painful that two separate approaches emerged in large part to sidestep it.
ORMs
One of the early things people tried was to map non-SQL code to SQL. The 90s saw TOPLink and then later Enterprise JavaBeans, both examples of something called Object Relational Mapping (ORM). They helped engineers write traditional code, organized into modules, files, and functions. It was a bit like ordering at a restaurant in a foreign country where the waiter speaks both the local language and your language but is not native in either. You usually get what you ask for, but not always. Some ORMs were better than others but no real system used them without heavy use of the escape hatch they all come with: the ability to write raw SQL — that is, speak to the chef directly in the local language. The downside was that SQL was then sprinkled randomly throughout the source code of another language in a way that once again made it hard to reason about. Tools aimed at the native language proved largely useless in managing the bits of SQL woven into Python, or Ruby, or whatever the app was written in, in the same way that a coin sorting machine can’t do anything with bills. In many apps, the resulting complexity of managing the database often entirely eclipsed the actual business logic — the thing that made your app special — which ended up being a tiny part of the actual engineering effort. ORMs also brought migration tools, like Rails migrations and Alembic, which made the tower of changes easier to write but no easier to read.
NoSQL
Eventually, there was a global revolt against SQL that cropped up somewhere between 2006 with Google’s Bigtable paper and 2009, which saw Cassandra, MongoDB, CouchDB, Redis, and others proudly aligning themselves with the NoSQL movement. Mongo was very easy to get going with and iterate on but SQL still won out for a host of reasons. Chief among them was that the data model didn’t just magically disappear — it became an emergent property of the code, which essentially spread the same poison migrations carried into the entire code base. The code became state. And so, after a long hype cycle, in 2023, Postgres became the most-used database in the Stack Overflow developer survey and SQL reasserted its dominance.
The end state
The point of pgdeclare is to let people write in SQL but describe the final state without building up an ever less stable tower of changes. Reverse jenga still ends up with a pile of blocks on the floor — it’s just a bigger mess. To set expectations: some change management is inevitable and we provide our own escape hatch for that. And to be fair, pgdeclare is not the first schema differ — even for Postgres — but we couldn’t find a free, open-source one that handled the SQL our code uses. Hopefully it works for you too, and if not, pull requests are very welcome.